How to Deploy Local LLMs for Embedded Software Development: The Inference Stack and Honest Comparison
In the first part of this series, I outlined the motivation for creating a self-hosted local LLM. The main reasons included client confidentiality, data sovereignty, offline reliability, and the unpredictability of token pricing. I also defined relevant terminology and how they translate into model selection. In the second part, I mapped model parameters into hardware requirements and described how I landed on a pair of Nvidia DGX Sparks.
In this part, I will cover the experiment I ran on the different models that would fit on my hardware and the model I ultimately settled on. To my surprise, the model that performed best in my experiment wasn't the one with the most parameters.
The Approach
One of the questions I struggled with was to correctly evaluate a particular model against a frontier model (specifically, Claude Code running Opus 4.8). The challenge was that Claude Code in its entirety isn't just an LLM. Instead, it performs a fair bit of work behind the scenes and is powerful even on its own. Thus far, my use and evaluation of local LLMs have been to create custom scripts to serve as a chatbot for the model or to use a tool such as OpenCode. I have been evaluating the quality of the model based on how frustrated I get with the model, either by how many times we circle back on the same change after testing or how many obvious errors it makes. Ultimately, I go through the same exercise using Claude Code to arrive at a final result. Obviously, this method is not very scientific. First, I needed to eliminate as many variables as possible so I could focus strictly on the model itself. I accomplished this with the following architecture (generated using Gemini):
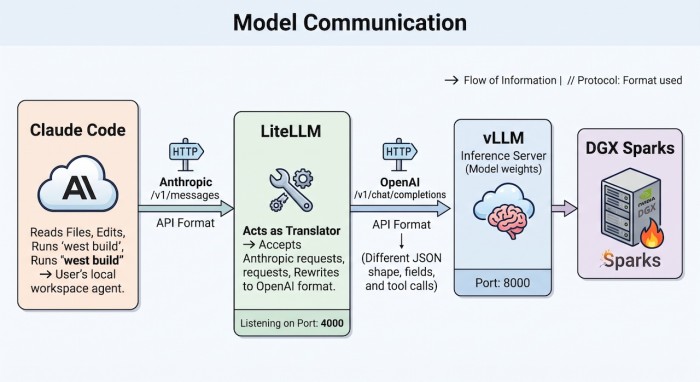
- Claude Code is the agent throughout the entire exercise. It reads and edits files and runs the appropriate compilation commands to ensure that, at a minimum, the changes compile successfully. Claude Code runs on the development machine.
- When it needs to communicate with a model, Claude Code uses Anthropic's message format.
- The local models are served via the vLLM inference server, which runs on my Nvidia DGX Sparks. The DGX Sparks also hold the model weights.
- The vLLM server only communicates using OpenAI's message format and thus can't natively communicate with Claude Code.
- LiteLLM, which also sits on the DGX Sparks, serves as a translator between Claude Code and the vLLM inference server. It accepts requests in Anthropic's message format, translates them into OpenAI's message format, and forwards them to the vLLM server.
Now that I have a way to eliminate the variability across different local and Anthropic models, I needed an accurate way to evaluate them. Public benchmarks are not very useful to me, since I only care about how well the models perform on a few specific types of embedded software projects (namely, Zephyr and Embedded Linux).
I've outlined the models I tried below along with their number of model weights and the number of Sparks needed to run them:
| Model Name | Number of Parameters | Number of Sparks Used |
| Qwen3-Coder-Next | 80 billion | 1 |
| Minimax-M2.7 | 228 billion | 2 |
| DeepSeek V4-Flash | 156 billion | 2 |
| Claude Code (Opus 4.8) - baseline | N/A | N/A |
Results and Next Steps
I evaluated each of the above models against a client project based on the Zephyr Project. I removed sensitive information so that only generalized subsystems are exposed to the models (and, more specifically, Claude Code). I selected a specific commit in the project's history and asked each model to make the necessary changes to produce the next commit. I chose this because I knew the correct answer, having written and tested the change myself. My implementation served as a reference for what a working solution looks like. However, I didn't want to bias the outcome against any particular implementation.
The pass/fail criterion was surprisingly simple. If the change caused the command to build the Zephyr project (i.e., `west build`) to succeed, that would be considered a passing result. If west reported an error, that would be considered a failing result. Due to the stochastic nature of the models, I prompted each model multiple times to evaluate its pass/fail result, which is shown below:
- Qwen3-Coder-Next: Passed 0/3 times (all attempts failed)
- Minimax-M2.7: Passed 0/3 times (all attempts failed)
- DeepSeek V4-Flash: Passed 3/3 times (all attempts succeeded)
- Claude Opus 4.8: Passed 1/1 time
The reasons the first two models failed were also surprising. Both models fully explored the repository and called real functions in my code. However, the problem was the functions that they called. Qwen3-Coder-Next and Minimax-M2.7 called outdated functions that I had stubbed out during testing and didn't implement. DeepSeek V4-Flash, and my final implementation, which served as the source of truth, did make calls to functions that I implemented (instead of the stubs).
Additionally, the following were the timing results for DeepSeek V4-Flash and Claude Code:
| Model | Turns | Wall clock (seconds) | Runs passed |
| Claude Opus 4.8 | 34 | 552 | 1/1 |
| DeepSeek V4-Flash | 67 - 83 | 555 - 1586 | 3/3 |
As we can see, DeepSeek V4-Flash took at least twice as many turns, but in one instance, it successfully completed the task in almost the same amount of time as Claude Opus 4.8. However, it's important to keep in mind that the pass/fail criterion was rudimentary. Specifically, we only tested if the output of a model resulted in a successful compilation. Even with that, we were able to eliminate 2 out of 3 models from our selection. To correctly evaluate whether DeepSeek V4-Flash is a viable model, we would need to set up a complete test harness and grant the model access to it so it can more thoroughly evaluate the changes. I will cover that in a future blog post to properly evaluate DeepSeek V4-Flash against Claude Opus 4.8.
- Comments
- Write a Comment Select to add a comment
To post reply to a comment, click on the 'reply' button attached to each comment. To post a new comment (not a reply to a comment) check out the 'Write a Comment' tab at the top of the comments.
Please login (on the right) if you already have an account on this platform.
Otherwise, please use this form to register (free) an join one of the largest online community for Electrical/Embedded/DSP/FPGA/ML engineers: